Learning experiment · PyTorch
Transformer learning implementation
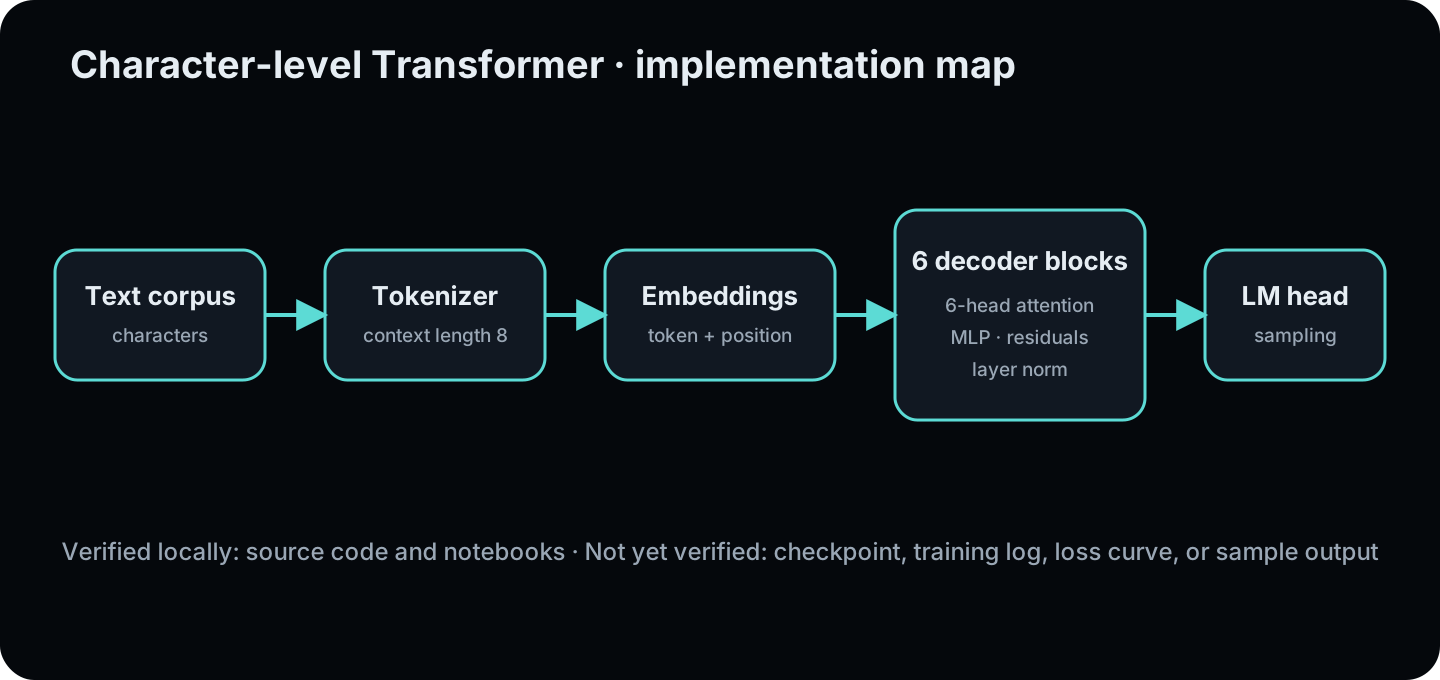
A tutorial-based character-level decoder implementation, developed with AI assistance to learn how attention and decoder blocks fit together.
A tutorial-based character-level decoder implementation, developed with AI assistance to learn how attention and decoder blocks fit together.
The notebooks explore token and positional embeddings, scaled dot-product attention, multiple attention heads, feed-forward blocks, residual connections and layer normalisation.
The implementation also includes data batching, training-loop and sampling code, with an Intel XPU execution path.